
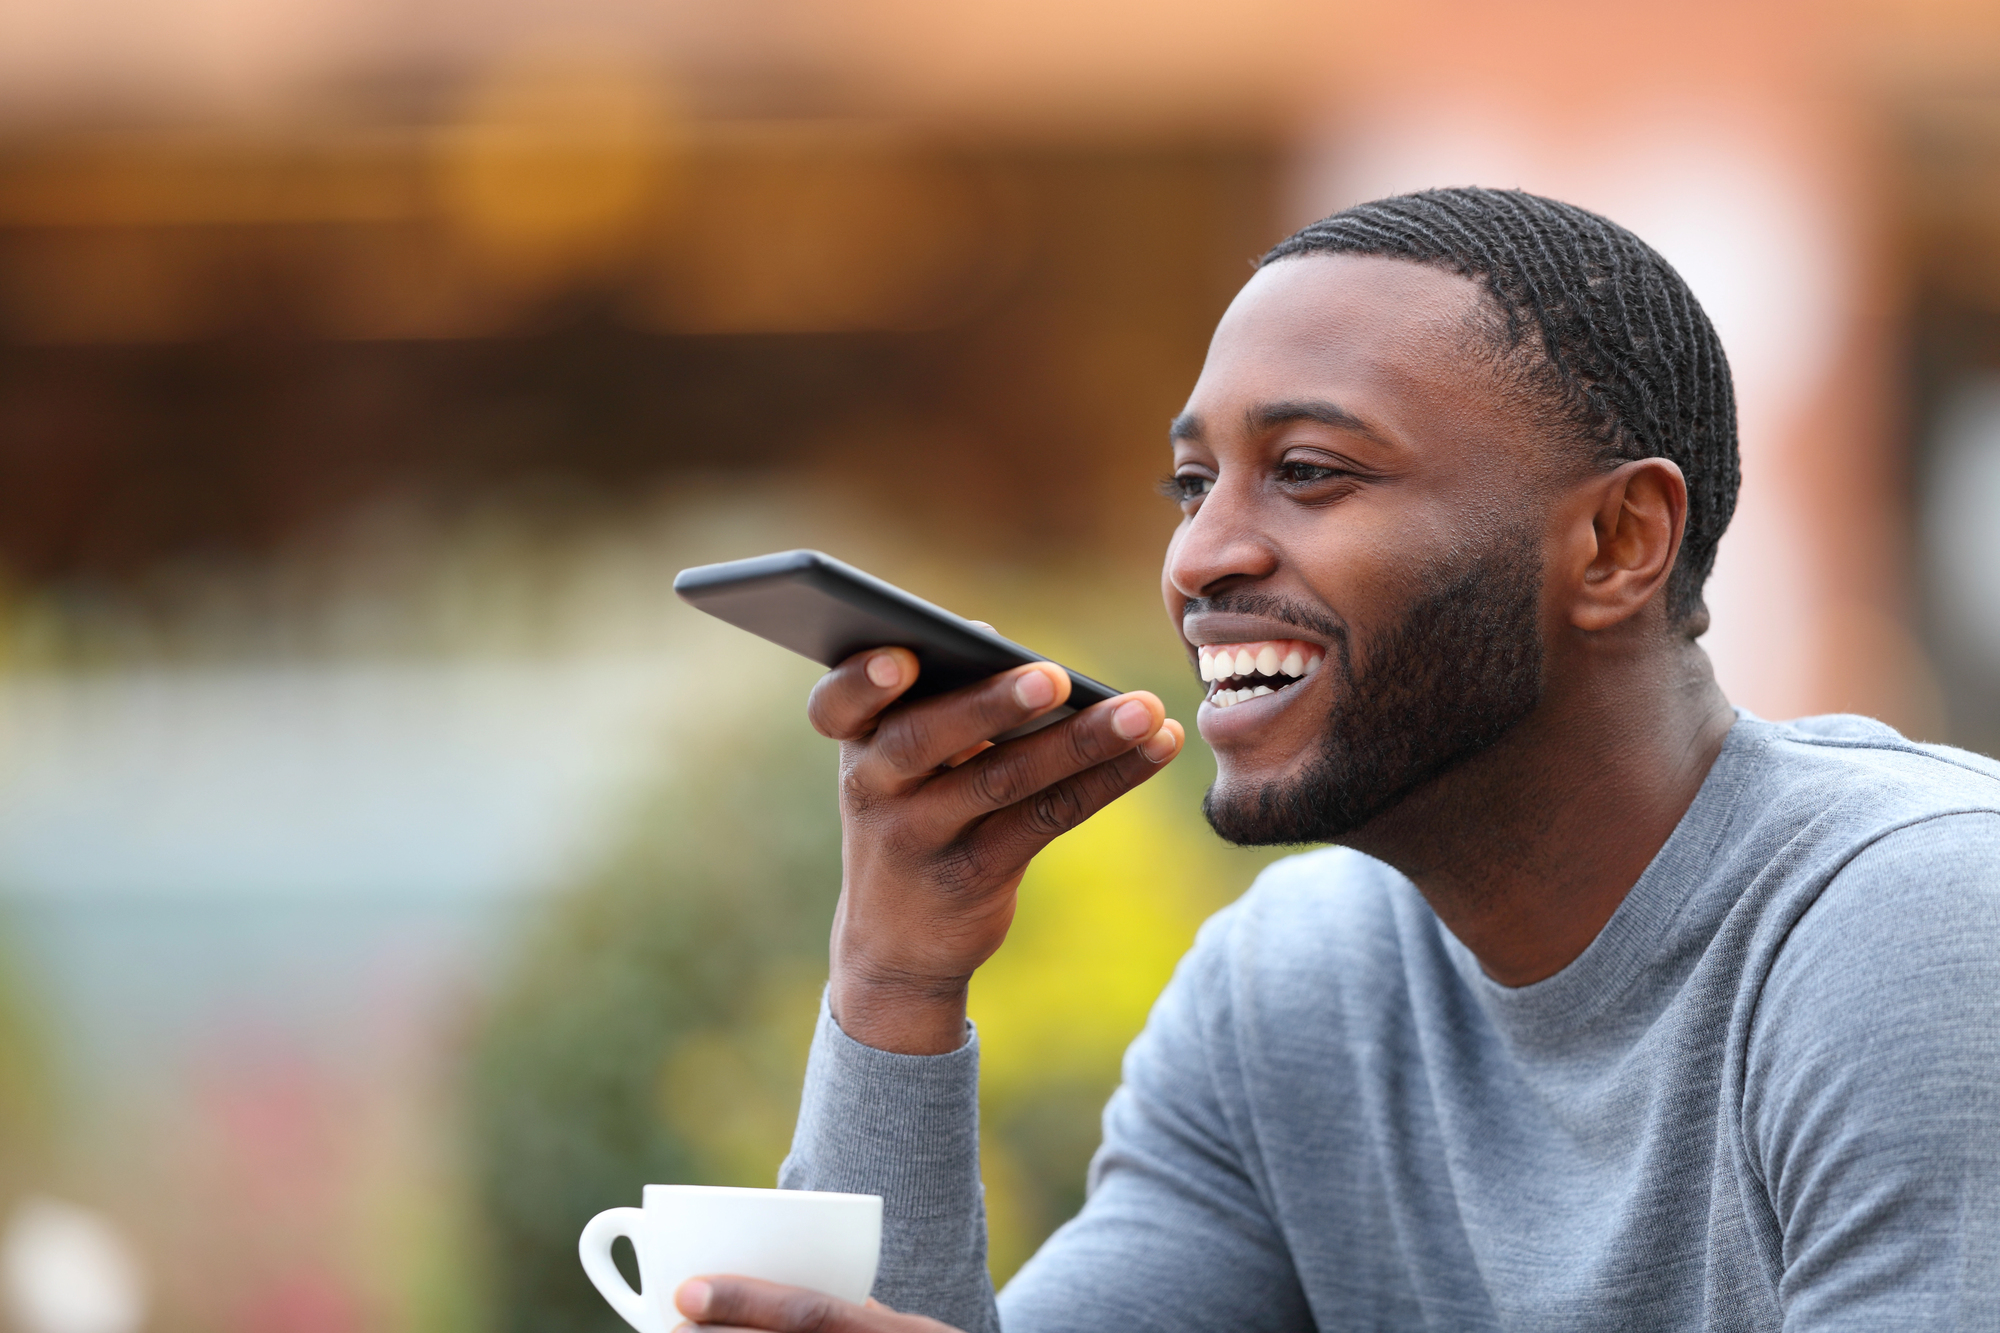
For millions of Black Americans using voice-activated technology, speaking to a smart assistant often comes with an unspoken requirement: altering their natural cadence, accent, and diction just to be understood. Now, a new initiative from Howard University and Google Research is set to eliminate that implicit barrier.
Through Project Elevate Black Voices, researchers have officially released the Howard African American English Dataset 1.0, a massive collection of 600 hours of natural African American English (AAE) audio collected across 32 states. The goal? Ensuring artificial intelligence developers can train automatic speech recognition (ASR) systems to accurately understand and process Black voices without requiring users to code-switch.
African American English (also referred to as African American Vernacular, Black English, or Ebonics) heavily influences global pop culture, music, and mainstream speech. However, because computational systems have historically lacked inclusive speech data, voice assistants frequently misconstrue commands, fail to process different syllables, or return incorrect responses when interacting with Black users.
“African American English has been at the forefront of United States culture since almost the beginning of the country,” explained Gloria Washington, Ph.D., Howard University researcher and co-principal investigator of Project Elevate Black Voices. “Voice assistant technology should understand different dialects of all African American English to truly serve not just African Americans, but other persons who speak these unique dialects. It’s about time that we provide the best experience for all users of these technologies.”
Researchers found that because Black users have been implicitly conditioned over time to change their natural voice patterns when speaking to tech, “unaccommodated” AAE speech is rarely found in existing public datasets.
To capture authentic, unforced speech, researchers organized community activations across multiple cities. These events featured Black panelists who live and work in those communities, facilitating open discussions on Black culture, technological bias, and data privacy. Attendees were then invited to contribute their voices to a three-week audio collection drive.
“Speech recognition technology systems struggle with African American English because African American speech data isn’t inclusive within the data set,” shared a researcher in a project video release. “Project Elevate Black Voices is a large-scale data set collection of African American English where we went all over the United States to collect different regional dialects… The foundation of any machine learning model is always the data. And so we need really good data in order to be able to build systems that work well for everyone.”
Courtney Heldreth, Ph.D., co-principal investigator at Google Research, emphasized the personal and societal weight of the effort:
“Working with our outstanding partners at Howard University on Project Elevate Black Voices has been a tremendous and personal honor,” Heldreth stated. “It’s our mission at Google to make technology that’s useful and accessible, and I truly believe that our work here will allow more users to express themselves authentically when using smart devices.”
Howard University will retain full ownership and licensing rights of the dataset, acting as responsible stewards to ensure the data directly benefits Black communities.
Initially, the Howard African American English Dataset 1.0 will be made available exclusively to researchers and institutions within Historically Black Colleges and Universities (HBCUs). This guarantees that marginalized linguistic practices are first explored and developed by institutions aligned with community empowerment and ethical research before broader commercial release is considered.
Google will also leverage the dataset to train its internal models, improving its smart devices and voice tools for a wider audience worldwide.
“It’s really important that the community have ownership over this dataset, that they know that their participation and their voices will actually make a difference,” a project researcher highlighted in the release video. “I hope that this project is a great example of how communities, corporations, and universities can all collaborate and push innovation forward.”